whatsapppopupnewiconGUIDE ME

Join Databricks Training in Hyderabad at Croma Campus to master Spark, SQL, data engineering, and hands-on projects.

4.9 out of 5 based on 12545 votes
google4.2/5
Sulekha4.8/5
Urbonpro4.6/5
Just Dial4.3/5
Fb4.5/5

In collaboration with

400+

Corp. Tie-Ups

Online/Offline

Format

LMS

Life Time Access

Book A Free Counselling Session

we train you to get hired.

bag-box-form
Request more information_

  • Databricks Training in Hyderabad enables the learners to understand the process of handling Big Data, creating data pipelines, and data management through Databricks technology. The topics included in the curriculum are Spark, PySpark, and Delta Lake. Databricks is a tool that is used by businesses to analyze huge amounts of data. It is used to perform data cleaning and processing, creating data pipelines and preparing data for reporting.
  • For instance, an e-commerce organization receives a huge number of orders daily, and its data team should collect and prepare the data for further analysis. The Databricks tool can be used in this case in order to automate such operations via notebooks, data processing utilities and scheduling workloads.The Databricks Course in Hyderabad can be used by students in order to understand the functionality of the Databricks tool and how it is used in data engineering and data analytics. The courses provide training on Lakehouse platform, Apache Spark, PySpark, Delta Lake and data pipelines.

Databricks Training in Hyderabad

About-Us-Course

  • This course is valuable not only for beginners but also for those who work and those who wish to develop competencies in the domain of data engineering. Practical exercises will enable students to grasp how data travels from source to destination. The course covers the main tools and tasks used to work with data in Databricks.
    • Introduction to Databricks and the Lakehouse platform.

      Databricks workspace and notebooks.

      Apache Spark basics.

      PySpark and DataFrames.

      Spark SQL and data queries.

      Data cleaning and transformation.

      Delta Lake and Delta tables.

      Data ingestion from different sources.

      Building and managing data pipelines.

      Jobs and workflows.

      Data storage and processing.

      Unity Catalog and data access basics.

      SQL analytics and reporting, where included.

      Performance basics and troubleshooting.

      Practical assignments and end-to-end projects.

  • The objective of taking the Databricks Course is for students to be able to learn about how data collection, processing, storage, and preparation are done.
    • Understand the main features of Databricks.

      Work with notebooks and the Databricks workspace.

      Learn the basics of Apache Spark and PySpark.

      Read and process data using DataFrames.

      Clean and transform data.

      Understand Delta Lake and Delta tables.

      Learn how data pipelines are built.

      Work with basic Spark SQL queries.

      Understand how jobs and workflows are scheduled.

      Learn the basics of data access and governance.

      Practise data engineering tasks through sample projects.

  • It is important that the course will teach students how all the processes are interconnected rather than how the separate tools work individually. It is necessary for the students to study the skills of reading the source data, modifying it, storing the result and making sure everything works properly. The role of jobs in the data pipeline can be considered too.
  • Course Highlights
    • Live instructor-led classes.

      Databricks platform introduction.

      Workspace and notebook practice.

      Apache Spark and PySpark basics.

      DataFrames and Spark SQL.

      Data cleaning and transformation exercises.

      Delta Lake practice.

      Data ingestion and pipeline building.

      Jobs and workflow management.

      Unity Catalog overview, if included

      Practical assignments and projects.

      Doubt-clearing sessions.

      Interview preparation, if offered.

      Resume guidance, if offered.

      Certification guidance, if offered.

      Online or classroom batches, depending on availability.

      Weekday and weekend classes, depending on the schedule.

  • Eligibility Criteria
    • Fresh graduates and students.

      Software developers.

      Data analysts.

      Data engineers.

      Python and SQL professionals.

      Cloud computing professionals.

      Business intelligence professionals.

      IT professionals looking to learn data tools.

      Working professionals who want to improve their data skills.

      Job seekers interested in data engineering.

  • Databricks training in Hyderabad would prove useful for individuals interested in how businesses manage big data. Data analysts could discover the process of preparing data for querying and reporting. Python and SQL developers could get an idea of how their expertise is applied to Databricks for data processing. Cloud computing and data engineers could benefit as well if they wanted to know more about data pipelines, Delta Lake and workflows. Even freshers could enrol if the course provides the necessary knowledge and practice.

  • Databricks and the Lakehouse Platform
    • The students get to know the functions of Databricks and the Lakehouse which integrates all data processes like data engineering, analytics, and many more data related processes.

      The students get to know the functions of Databricks and the Lakehouse which integrates all data processes like data engineering, analytics, and many more data related processes.

      In this course, the students learn the use of the workspace and notebooks to perform coding, execute queries, and process data. Notebooks help in keeping track of the code and the results of the code at each stage.

      Apache Spark is used for processing Big Data. PySpark allows the user to perform operations on Spark using the Python language. The students are taught basic operations on Spark along with DataFrame and transformations on data.

      Actual data includes errors like missing data, duplicates, and inaccuracies. The course teaches students about data cleaning, transformation and preparing data for further usage.

      Delta Lake is a set of functions like table transactions and updates that is available for data that is stored in a Lakehouse. Students get acquainted with the basics of Delta tables and understand the usage of Delta tables in working with data.

      Students are taught how to ingest data from various sources to Databricks and how to assemble data processing steps into a pipeline.

      Jobs and workflows allow for planning the execution of data tasks in certain order. This course provides students with knowledge about scheduling of tasks, results verification and error handling.

      If included in the curriculum, students learn how Unity Catalog can be used to control access to data and other resources. Students are able to understand the necessity of permission control and restricted access to data by various teams.

  • Data Cleaning and Transformation
    • Actual data includes errors like missing data, duplicates, and inaccuracies. The course teaches students about data cleaning, transformation and preparing data for further usage.

      Delta Lake is a set of functions like table transactions and updates that is available for data that is stored in a Lakehouse. Students get acquainted with the basics of Delta tables and understand the usage of Delta tables in working with data.

      Students are taught how to ingest data from various sources to Databricks and how to assemble data processing steps into a pipeline.

      Jobs and workflows allow for planning the execution of data tasks in certain order. This course provides students with knowledge about scheduling of tasks, results verification and error handling.

      If included in the curriculum, students learn how Unity Catalog can be used to control access to data and other resources. Students are able to understand the necessity of permission control and restricted access to data by various teams.

  • Why Are Businesses Using Databricks
    • Managing big volumes of data: Databricks helps manage data for business and technical purposes.

      Data cleaning: Data can be prepared for use through error correction and transformation.

      Data pipelines: Data processing activities can be arranged in the form of repeatable pipelines.

      Supporting different data activities: The solution provides support for data engineering, SQL analytics, and other data-related activities.

      Collaboration: Team members can cooperate when working on data-related tasks using notebooks and resources.

      Data access management: Governance functionality helps organizations to manage access to data and other resources.

  • Upon completion of the Databricks Coaching in Hyderabad, they will be able to seek employment in roles that relate to data engineering and data processing analysis. The type of jobs that they will qualify for will vary based on prior skills and experience.
  • Possible Job Roles Include
    • Databricks Developer.

      Data Engineer.

      Junior Data Engineer.

      PySpark Developer.

      Big Data Engineer.

      Data Processing Engineer.

      Data Analyst.

      Cloud Data Engineer.

      Data Platform Engineer.

      ETL Developer.

  • Job Roles You Can Opt For
    • Developer for Databricks: Works with Databricks Notebooks and data processing operations.

      Data Engineer: Designs and develops systems used to extract, process and structure data.

      PySpark Developer: Processes and transforms data using Python and Spark.

      Big Data Engineer: Develops systems for processing big data.

      Data Analyst: Analyzes structured data and helps make business decisions based on that analysis.

      Cloud Data Engineer: Works with data systems in the cloud environment.

  • Tool or Area
    • Databricks: Workspace, notebooks and data processing.

      Apache Spark: Processing large amounts of data.

      PySpark: Using Python with Spark.

      DataFrames: Reading, changing and processing data.

      Spark SQL: Writing queries for data.

      Delta Lake: Managing reliable data tables.

      Data Pipelines: Connecting data processing steps.

      Jobs and Workflows: Running tasks in a planned order.

      Unity Catalog: Basics of data access and governance.

      SQL Analytics: Querying and reviewing data, if included.

  • Projects Included in the Course
    • Data Cleaning Project: Clean a dataset containing missing values, repeated records and incorrect details.

      PySpark Project: Read a dataset and perform basic transformations using PySpark.

      Delta Lake Project: Store and update data using Delta tables.

      Data Pipeline Project: Build a sample pipeline to process data from source to output.

      SQL Analytics Project: Write queries to answer questions from a sample dataset.

      Workflow Project: Set up a sample workflow and review its execution.

      End-to-End Data Engineering Project: Combine data ingestion, cleaning, transformation and storage into one process.

      The Databricks course should include practical exercises along with theory. Students can practise using notebooks, reading data, writing queries, cleaning records and saving results. They should also learn how data pipelines work and how to check the output when a task is completed. Projects can help students connect Spark, PySpark and Delta Lake instead of learning each topic separately.

      Before joining, check whether the institute provides hands-on Databricks access and whether you will complete projects yourself.

  • Students interested in official Databricks certification should check the latest options on the official Databricks website. The platform offers learning paths for different roles, including data engineers and data analysts. Training and certification are not the same thing. Before enrolling, confirm whether the course includes certification preparation, an exam voucher or only general guidance. Check the current exam requirements and fees through the official website.

  • The duration of Databricks Training in Hyderabad depends on the syllabus, class hours and practical work included. Before joining Databricks Coaching in Hyderabad, check the total training hours, Python and SQL requirements, hands-on access, project work, trainer experience and available batch timings. Make sure the course gives you enough time to practise the main data processing tasks.

  • The fees for a Databricks course can vary based on the institute, training duration, batch type, practical access and support offered. Before paying, check whether the fee includes the complete syllabus, study material, recorded classes, practical projects, cloud or platform access, certification guidance and interview preparation. Ask about any extra charges before enrolling.
    • Python and SQL: These skills help you work with data and understand queries.

      Hands-on practice: Practise reading, cleaning and processing data.

      Project experience: Build projects that show how data moves through a pipeline.

      Spark knowledge: Understand how Apache Spark processes data.

      Delta Lake knowledge: Learn how data tables are stored and managed.

      Problem-solving skills: Learn to check errors and understand why a pipeline may fail.

  • Why Students Choose Us
    • Simple Teaching: Topics are explained step by step to help students understand the platform.

      Hands-on Learning: Practical exercises help students learn how data is processed.

      Project Work: Projects connect different tools and show how a data pipeline works.

      Trainer Support: Students can ask questions and review difficult topics.

      Doubt Sessions: Available sessions can help students understand challenging concepts.

      Interview Preparation: If offered, practice sessions can help students explain their projects and technical skills.

      Resume Support: If included, guidance can help students present their skills and project work.

      Career Assistance: Check whether the institute provides interview practice, job search support or placement assistance.

  • Our Databricks Training Institute in Hyderabad aims to explain data processing concepts in simple language. Students can learn about notebooks, Spark, PySpark, Delta Lake and data pipelines, depending on the selected batch.
  • Databricks Coaching in Hyderabad may include practical exercises, project work, doubt-clearing sessions and interview preparation, depending on the services offered. Check the complete syllabus, platform access and available support before joining.

Why Should You Learn Databricks?

Not just learning

we train you to get hired.

bag-box-form
Request more information

By registering here, I agree to Croma Campus Terms & Conditions and Privacy Policy

CURRICULUM & PROJECTS

Databricks Certified Data Engineer Associate Training Program

    Describe the relationship between the data lakehouse and the data warehouse.

    Identify the improvement in data quality in the data lakehouse over the data lake.

    Compare and contrast silver and gold tables, which workloads will use a bronze table as a source, which workloads will use a gold table as a source.

    Identify elements of the Databricks Platform Architecture, such as what is located in the

    data plane versus the control plane and what resides in the customer’s cloud account

    Differentiate between all-purpose clusters and jobs clusters.

    Identify how cluster software is versioned using the Databricks Runtime.

    Identify how clusters can be filtered to view those that are accessible by the user.

    Describe how clusters are terminated and the impact of terminating a cluster.

    Identify a scenario in which restarting the cluster will be useful.

    Describe how to use multiple languages within the same notebook.

    Identify how to run one notebook from within another notebook.

    Identify how notebooks can be shared with others.

    Describe how Databricks Repos enables CI/CD workflows in Databricks.

    Identify Git operations available via Databricks Repos.

    Identify limitations in Databricks Notebooks version control functionality relative to Repos.

Get full course syllabus in your inbox

    Extract data from a single file and from a directory of files

    Identify the prefix included after the FROM keyword as the data type.

    Create a view, a temporary view, and a CTE as a reference to a file

    Identify that tables from external sources are not Delta Lake tables.

    Create a table from a JDBC connection and from an external CSV file

    Identify how the count_if function and the count where x is null can be used

    Identify how the count(row) skips NULL values.

    Deduplicate rows from an existing Delta Lake table.

    Create a new table from an existing table while removing duplicate rows.

    Deduplicate a row based on specific columns.

    Validate that the primary key is unique across all rows.

    Validate that a field is associated with just one unique value in another field.

    Validate that a value is not present in a specific field.

    Cast a column to a timestamp.

    Extract calendar data from a timestamp.

    Extract a specific pattern from an existing string column.

    Utilize the dot syntax to extract nested data fields.

    Identify the benefits of using array functions.

    Parse JSON strings into structs.

    Identify which result will be returned based on a join query.

    Identify a scenario to use the explode function versus the flatten function

    Identify the PIVOT clause as a way to convert data from wide format to a long format.

    Define a SQL UDF.

    Identify the location of a function.

    Describe the security model for sharing SQL UDFs.

    Use CASE/WHEN in SQL code.

    Leverage CASE/WHEN for custom control flow.

Get full course syllabus in your inbox

    Identify where Delta Lake provides ACID transactions

    Identify the benefits of ACID transactions.

    Identify whether a transaction is ACID-compliant.

    Compare and contrast data and metadata.

    Compare and contrast managed and external tables.

    Identify a scenario to use an external table.

    Create a managed table.

    Identify the location of a table.

    Inspect the directory structure of Delta Lake files.

    Identify who has written previous versions of a table.

    Review a history of table transactions.

    Roll back a table to a previous version.

    Identify that a table can be rolled back to a previous version.

    Query a specific version of a table.

    Identify why Zordering is beneficial to Delta Lake tables.

    Identify how vacuum commits deletes.

    Identify the kind of files Optimize compacts.

    Identify CTAS as a solution.

    Create a generated column.

    Add a table comment.

    Use CREATE OR REPLACE TABLE and INSERT OVERWRITE

    Compare and contrast CREATE OR REPLACE TABLE and INSERT OVERWRITE

    Identify a scenario in which MERGE should be used.

    Identify MERGE as a command to deduplicate data upon writing.

    Describe the benefits of the MERGE command.

    Identify why a COPY INTO statement is not duplicating data in the target table.

    Identify a scenario in which COPY INTO should be used.

    Use COPY INTO to insert data.

    Identify the components necessary to create a new DLT pipeline.

    Identify the purpose of the target and of the notebook libraries in creating a pipeline.

    Compare and contrast triggered and continuous pipelines in terms of cost and latency

    Identify which source location is utilizing Auto Loader.

    Identify a scenario in which Auto Loader is beneficial.

    Identify why Auto Loader has inferred all data to be STRING from a JSON source

    Identify the default behavior of a constraint violation

    Identify the impact of ON VIOLATION DROP ROW and ON VIOLATION FAIL UPDATEfor a

    constraint violation

    Explain change data capture and the behavior of APPLY CHANGES INTO

    Query the events log to get metrics, perform audit loggin, examine lineage.

    Troubleshoot DLT syntax: Identify which notebook in a DLT pipeline produced an error,

    identify the need for LIVE in create statement, identify the need for STREAM in from clause.

Get full course syllabus in your inbox

    Identify the benefits of using multiple tasks in Jobs.

    Set up a predecessor task in Jobs.

    Identify a scenario in which a predecessor task should be set up.

    Review a task's execution history.

    Identify CRON as a scheduling opportunity.

    Debug a failed task.

    Set up a retry policy in case of failure.

    Create an alert in the case of a failed task.

    Identify that an alert can be sent via email.

Get full course syllabus in your inbox

    Identify one of the four areas of data governance.

    Compare and contrast metastores and catalogs.

    Identify Unity Catalog securables.

    Define a service principal.

    Identify the cluster security modes compatible with Unity Catalog.

    Create a UC-enabled all-purpose cluster.

    Create a DBSQL warehouse.

    Identify how to query a three-layer namespace.

    Implement data object access control

    Identify colocating metastores with a workspace as best practice.

    Identify using service principals for connections as best practice.

    Identify the segregation of business units across catalog as best practice.

Get full course syllabus in your inbox

Course Design By

naswipro

Nasscom & Wipro

Course Offered By

croma-orange

Croma Campus

Real

star

Stories

success

inspiration

person1

Jitesh Verma

career upgrade

person1

Kartik

career upgrade

person1

Aman Kumar

career upgrade

person1

Sristi Rajput

career upgrade

SELF ASSESSMENT

Learn, Grow & Test your skill with Online Assessment Exam to
achieve your Certification Goals

right-selfassimage
Get exclusive
access to career resources
upon completion
quote
Mock Session

You will get certificate after
completion of program

laptop
LMS Learning

You will get certificate after
completion of program

star
Career Support

You will get certificate after
completion of program

Showcase your Course Completion Certificate to Recruiters

  • checkgreenTraining Certificate is Govern By 12 Global Associations.

  • checkgreen1Training Certificate is Powered by “Wipro DICE ID”
  • checkgreen2Training Certificate is Powered by "Verifiable Skill Credentials"

in Collaboration with

dot-line
Certificate-new-file

Not Just Studying

We’re Doing Much More!

Empowering Learning Through Real Experiences and Innovation

Mock Interviews

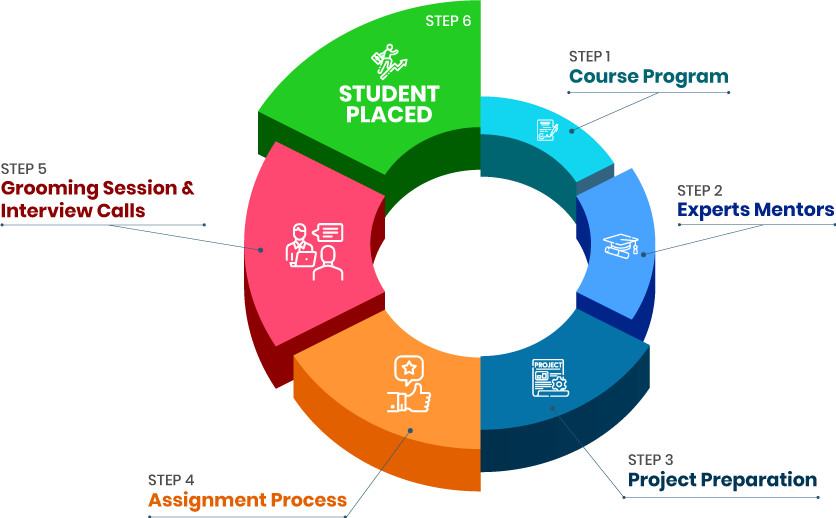
Prepare & Practice for real-life job interviews by joining the Mock Interviews drive at Croma Campus and learn to perform with confidence with our expert team.Not sure of Interview environments? Don’t worry, our team will familiarize you and help you in giving your best shot even under heavy pressures.Our Mock Interviews are conducted by trailblazing industry-experts having years of experience and they will surely help you to improve your chances of getting hired in real.
How Croma Campus Mock Interview Works?graph_new

Not just learning

we train you to get hired.

bag-box-form
Request A Call Back

Phone (For Voice Call):

‪+91-828 706 0032

WhatsApp (For Call & Chat):

+91-828 706 0032
          

Download Curriculum

Get a peek through the entire curriculum designed that ensures Placement Guidance

Course Design By

nasco wp

Course Offered By

Request Your Batch Now

Ready to streamline Your Process? Submit Your batch request today!

Students Placements & Reviews

speaker
Sanchit Nuhal
Sanchit Nuhal
speaker
Prayojakta
Prayojakta
speaker
Kapil Sharma
Kapil Sharma
speaker
Harikesh Panday
Harikesh Panday
speaker
Vikash Singh Rana
Vikash Singh Rana
speaker
Mohammad Sar
Mohammad Sar
View More arrowicon

FAQ's

Databricks is a platform that is used in data engineering, analytics, and other data-oriented activities. Databricks provides support for working with data, pipelines, and datasets.

Yes. Freshers may take into consideration this course but it would be better to have some experience in Python and SQL. It is important to find out whether the course covers the basics.

Python will come in handy when studying PySpark. There are some activities in Databricks that can be accomplished using SQL.

PySpark is the Python interface for Apache Spark. It allows users to process and transform data using Python.

Delta Lake enables data table management with capabilities like transaction processing and consistent updating.

In some Databricks Coaching in Hyderabad, there are practical projects related to data cleaning, PySpark, Delta Lake, and pipeline development. Verify the projects covered before joining.

This varies from one institute to another. Verify whether the training program includes any certification-related aspects.

Yes. Working professionals can join Databricks coaching based on their convenience.
Career Assistancecareer assistance
  • - Build an Impressive Resume
  • - Get Tips from Trainer to Clear Interviews
  • - Attend Mock-Up Interviews with Experts
  • - Get Interviews & Get Hired

Our learners
transformed their careers

highest
35 Laks

Highest Salary Offered

money
50%

Average Salary Hike

building
30K+

Placed in MNC’s

setting
15+

Year’s in Training

alumini
A majority of our alumni

fast-tracked into managerial careers.

Get inspired by their progress in the

Career Growth Report.

FOR VOICE SUPPORT

FOR WHATSAPP SUPPORT

sallerytrendicon1

Get Latest Salary Trends

×

For Voice Call

+91-971 152 6942

For Whatsapp Call & Chat

+91-9711526942
newwhatsapp
1
//